Not All Thoughts Need HBM: Semantics-Aware Memory Hierarchy for LLM Reasoning
Preprint · arXiv:2605.09490 · 2026-05-10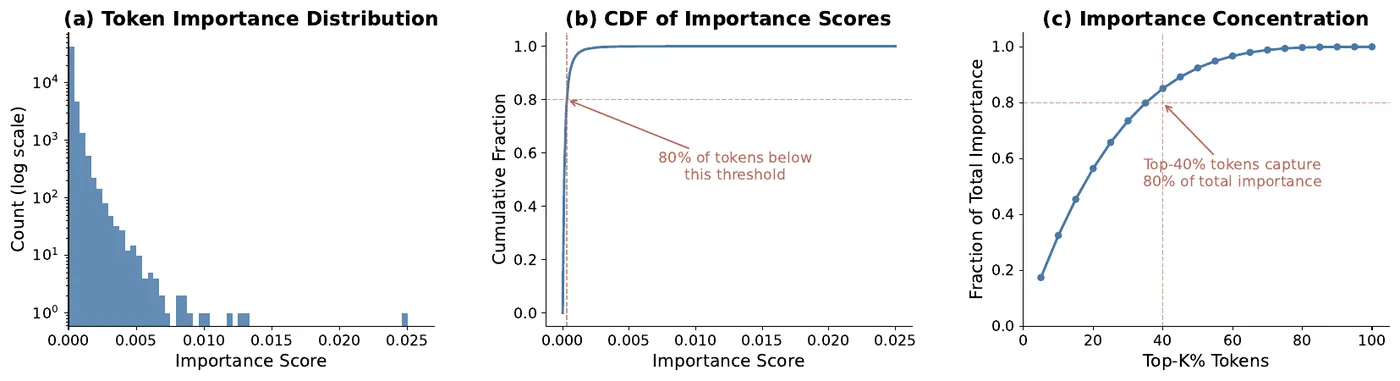
Abstract
Reasoning LLMs produce thousands of chain-of-thought tokens whose KV cache must reside in scarce GPU HBM. The dominant response -- permanently evicting low-importance tokens -- is catastrophic for reasoning: accuracy collapses to 0-2.5% when half the cache is removed. We ask a different question: must every token live in HBM, or can some live elsewhere? We introduce a semantics-aware memory hierarchy that sorts tokens into four tiers -- HBM, DDR, compressed, and evicted -- using cumulative attention scoring. Low-importance tokens are moved to CPU memory rather than destroyed; before each attention step they are prefetched back at full precision, contributing exactly the same terms as if they had never left the GPU. We formalize this as zero-approximation-error offloading and derive our central finding: accuracy depends solely on how many tokens are permanently discarded (the eviction ratio), not on how many remain in HBM. A controlled 3x3 grid over HBM and eviction ratios confirms this across three model scales (7B-32B) and four benchmarks. With only 3% eviction, the hierarchy retains 91% of full-cache accuracy on GSM8K and 71% on MATH-500 (n=200); at 14B scale it matches the uncompressed baseline (90% vs. 86%) while halving HBM occupancy. A head-to-head reproduction of R-KV -- the current SOTA eviction method -- on our setup achieves only 0-32% at comparable budgets. A system prototype with real GPU-CPU data movement shows that the price of this preservation is modest -- 5-7% transfer overhead -- and scaling analysis projects 2-48 GB HBM savings at production batch sizes.
Citation
@article{yuan2026not,
  title     = {Not All Thoughts Need HBM: Semantics-Aware Memory Hierarchy for LLM Reasoning},
  author    = {Yuan, Aojie and Shen, Tianqi and Zhang, Dajun},
  journal   = {arXiv preprint arXiv:2605.09490},
  year      = {2026},
  eprint    = {2605.09490},
  archivePrefix = {arXiv},
  doi       = {10.48550/arXiv.2605.09490},
  url       = {https://arxiv.org/abs/2605.09490}
}